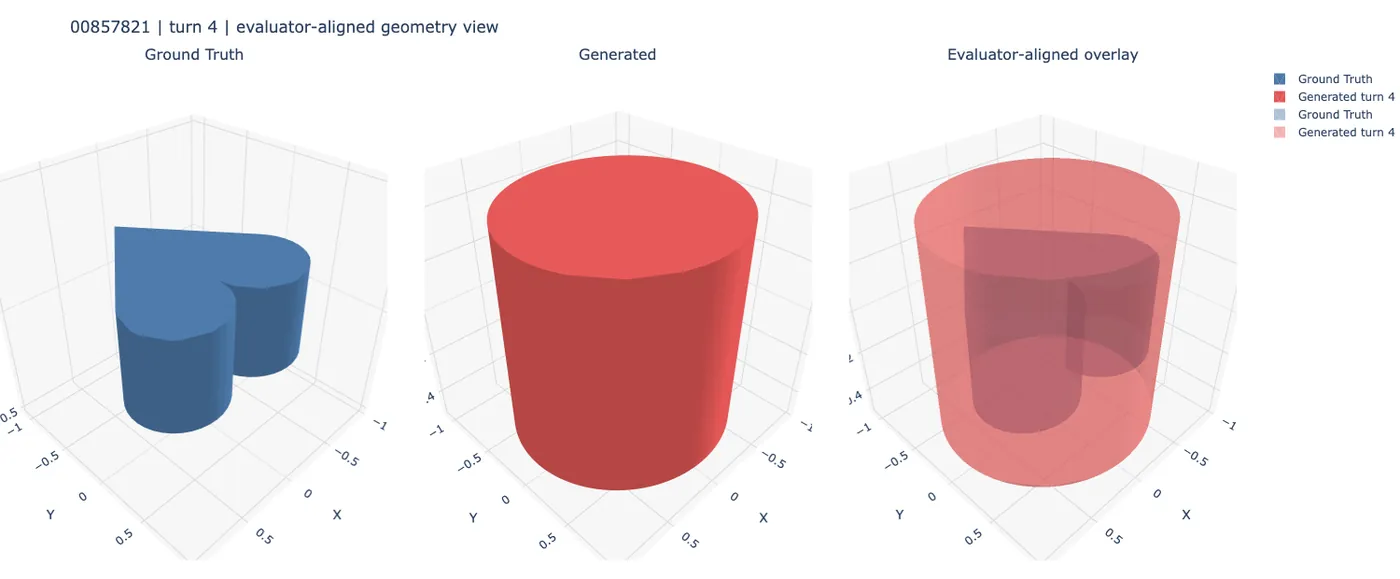
CAD repair on a frozen LLM, shape overlap Verified
0.82 → 0.92 voxel IoU, expert prompts
Expert prompts
Beginner prompts
Caveat. Repair is ground-truth-assisted. The target shape scores each attempt. No result without the target exists.
Evidence and numbers
- Baseline
- One-shot generation, same model (gpt-5.4-mini)
- Sample size
- 200 per group
- Setting
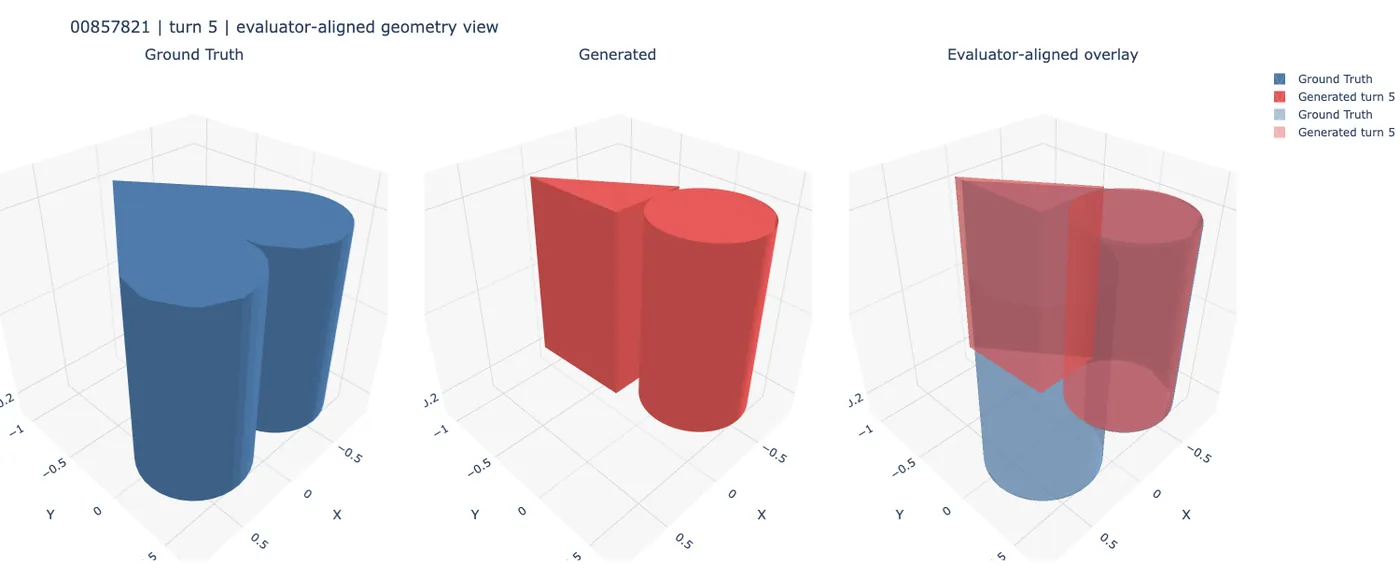
- LLM writes CadQuery, runs it, compares to the target part, repairs in at most 3 turns. Model is frozen.
- Evidence tier
- Verified. Re-read from a saved artifact (summary.csv).
- Agentic minus self-debug, paired bootstrap: +0.053 [0.019, 0.092] expert, +0.051 [0.023, 0.082] beginner (notebook output only).
- The three arms use different prompts.
Must-keep caveats
- Repair runs in repair_evidence_mode=gt_assisted: the ground-truth STL scores attempts. No GT-free result exists (gt_free is code/spec only; one small component pilot, spec 033 step2, 11 samples).
- Arms use different prompts (same LLM gpt-5.4-mini). Failed runs score IoU 0 and Hausdorff/Chamfer 2.0 (spec 024 sentinels).
- IoU is voxel IoU (pitch 0.05, ICP-aligned) per deep dive; CAD session did not independently verify voxel-based.
- Of 400 agentic runs: 393 evaluated, 7 runtime failures; geometry_correct 147/393; 83 of 230 loop 'successes' are geometry-wrong; turn 1 carries most of the gain.
| Group | Bar | Role | Value |
|---|---|---|---|
| Expert prompts | One-shot | baseline | 0.8227 |
| Expert prompts | Self-debug | comparison | 0.8633 |
| Expert prompts | Agentic repair | beat the baseline | 0.9163 |
| Beginner prompts | One-shot | baseline | 0.5688 |
| Beginner prompts | Self-debug | comparison | 0.6478 |
| Beginner prompts | Agentic repair | beat the baseline | 0.699 |